How to evaluate a RAG system without fooling yourself
A high retrieval score can still hide wrong answers. The reference sets, metrics and release gate I use to know whether a RAG change made answers better.
Read the postDashed underline marks text to replace
Notes from building LLM systems that run in production: what broke, how I measured it, and what fixed it.
A high retrieval score can still hide wrong answers. The reference sets, metrics and release gate I use to know whether a RAG change made answers better.
Read the postWhen health data cannot leave the building, the model has to come to the data. What self-hosting open-weight LLMs costs, and what it buys you.
An agent that sends reports or changes records should stop and ask first. How I build approval steps, retries and tracing into LangGraph workflows.
Embeddings miss exact codes, product names and section numbers that keyword search finds at once. Why my RAG systems combine BM25 and vector search.
What foundation models like SAM and CLIP got right on road scenes without labelled training data, where they failed, and how we measured it at Continental.
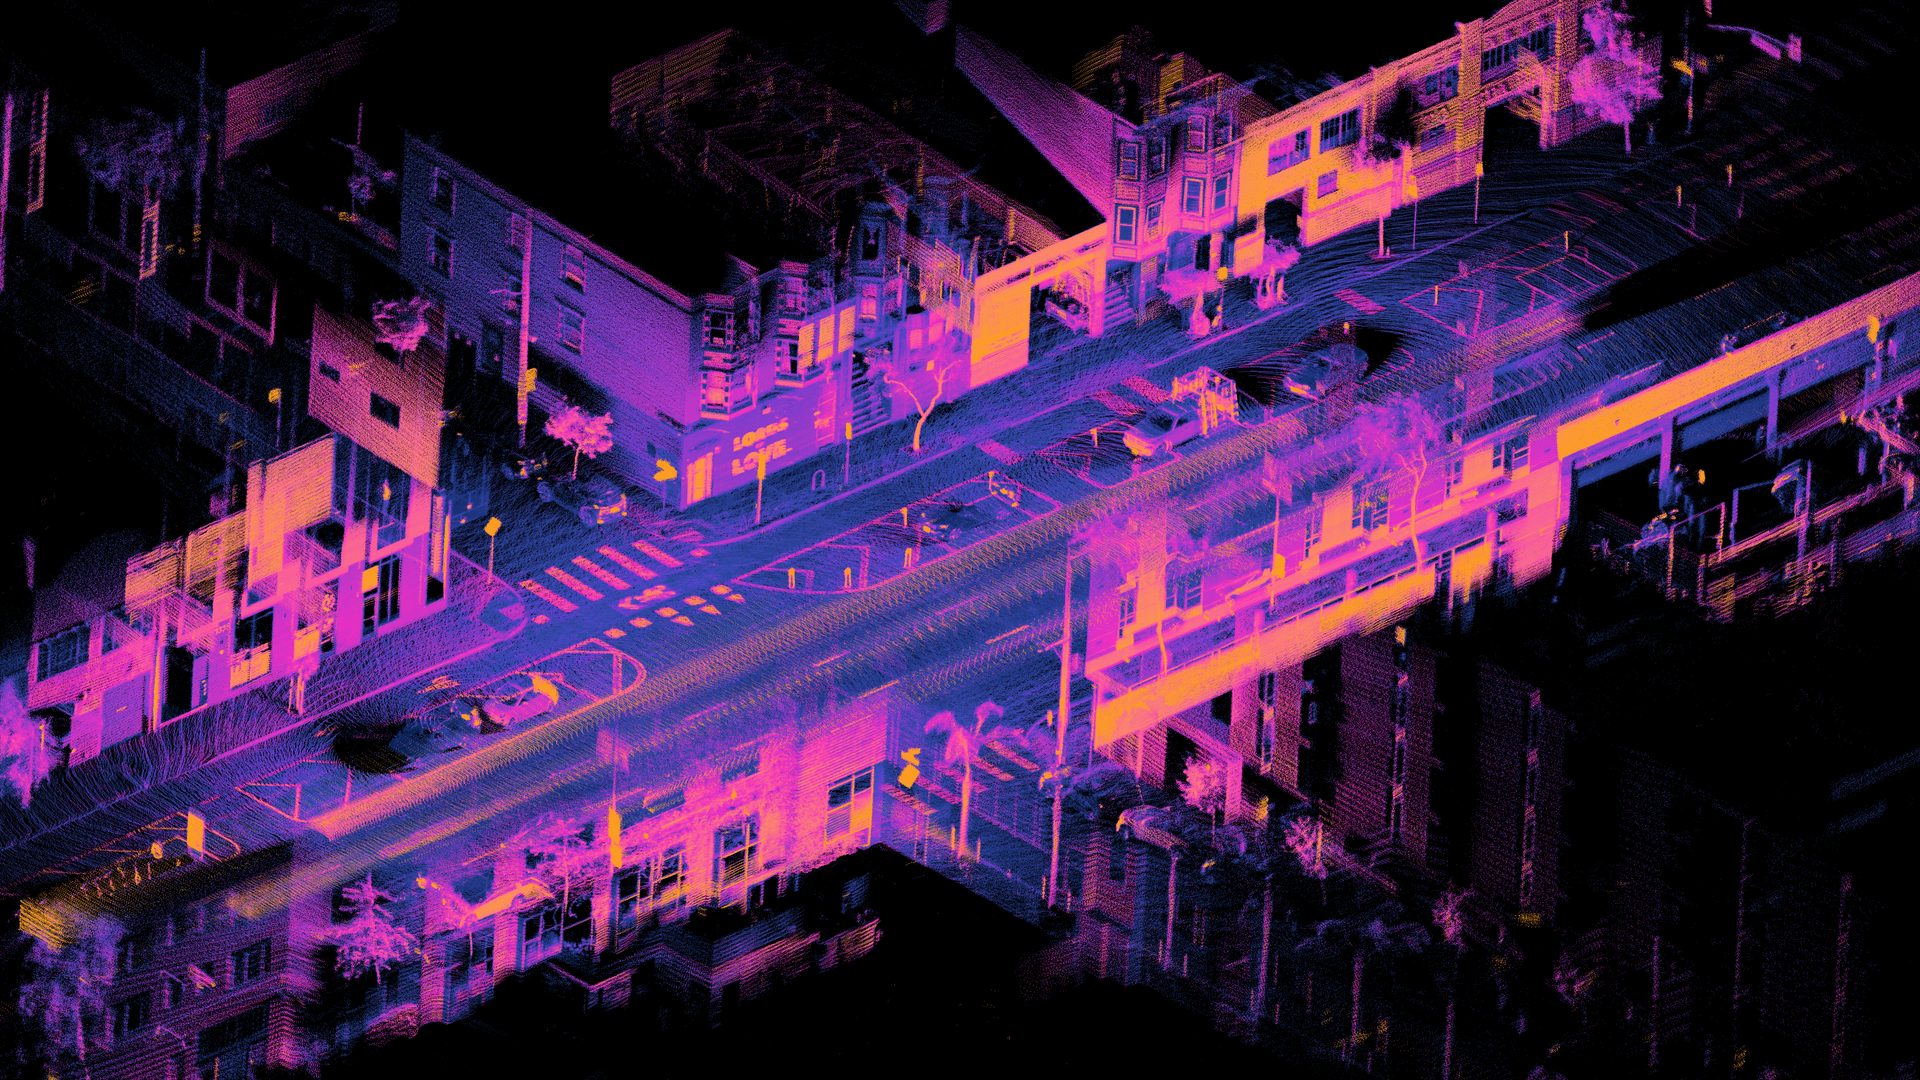
Labelling camera and LiDAR data is slow and expensive. How foundation-model pre-labels and camera-LiDAR fusion speed it up without lowering quality.
No other posts on this topic yet.