Zero-shot road segmentation with foundation models
What foundation models like SAM and CLIP got right on road scenes without labelled training data, where they failed, and how we measured it at Continental.
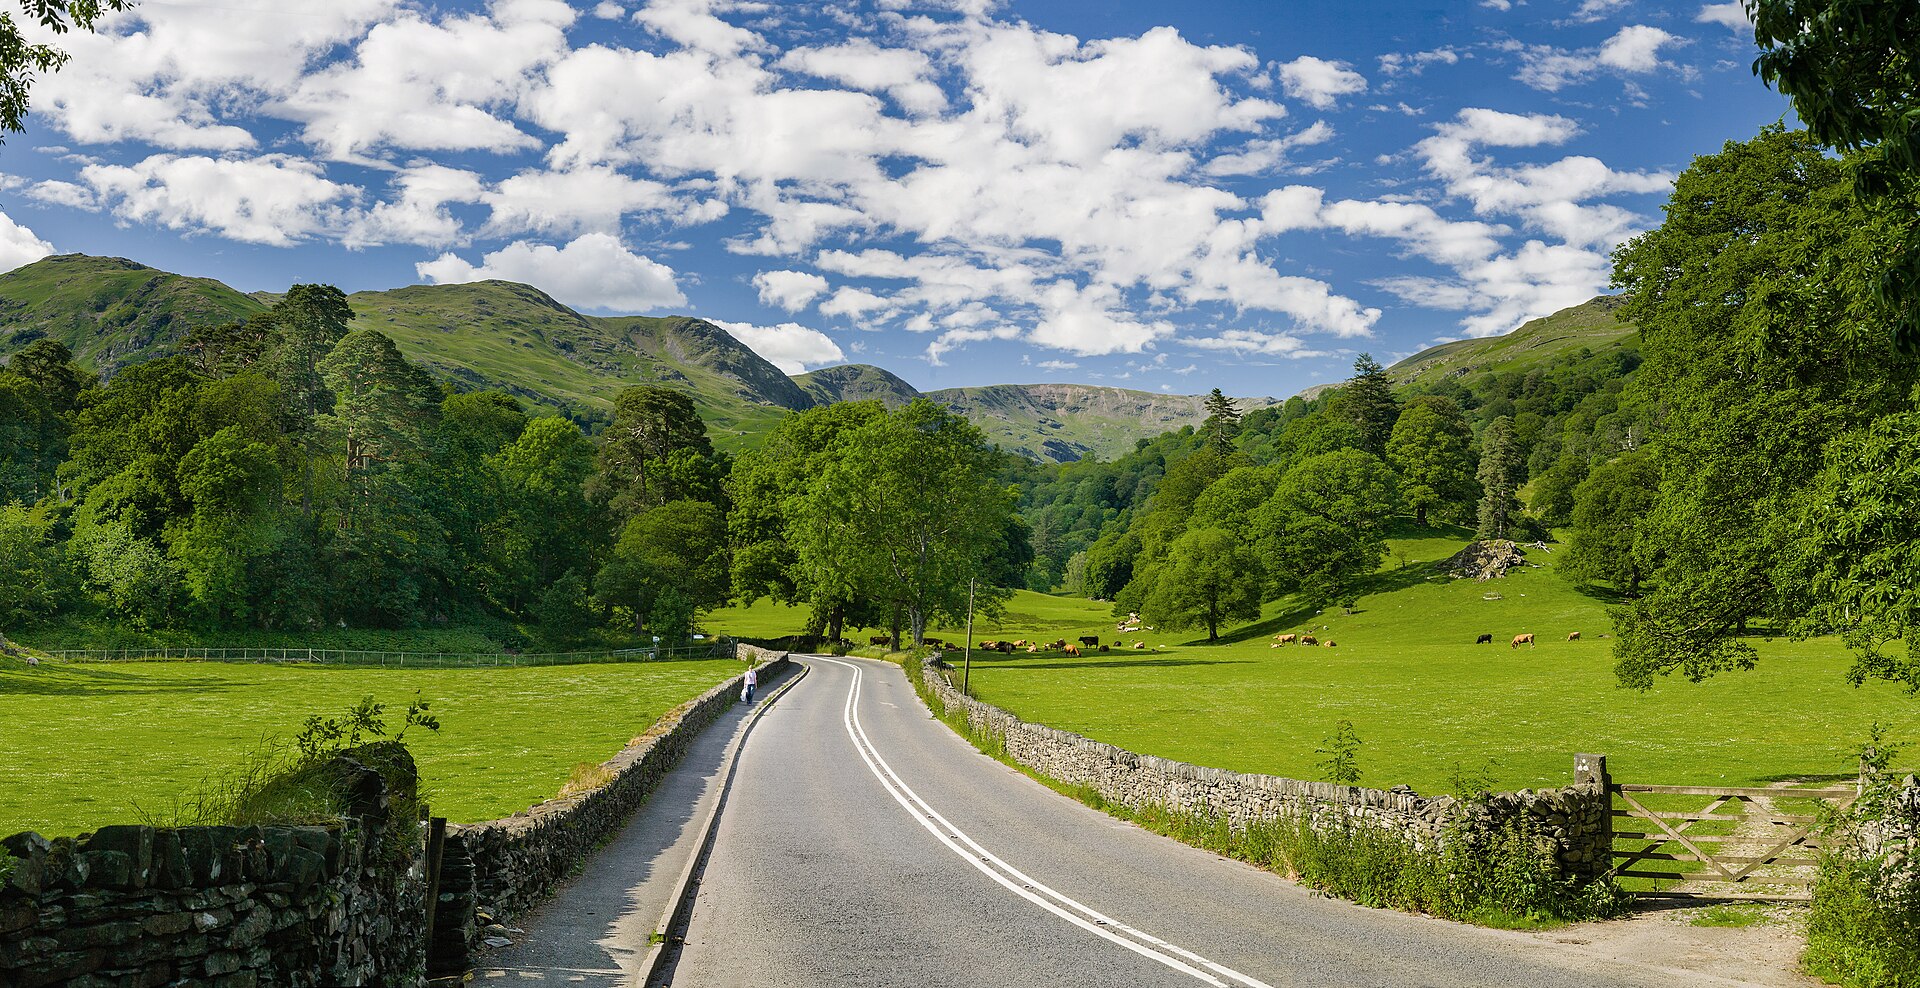
Training a road segmentation model usually starts with thousands of labelled images. At Continental, the question was whether foundation models could find the road with no task-specific training at all.
The approach
Segment Anything proposes masks for everything in the frame. A text prompt scored with CLIP decides which of those masks is road. SEEM handled the scenes where a single prompt was not enough.
What worked
The zero-shot pipeline reached 99% precision. That was enough to use its masks as pre-labels for the annotation team, which cut labelling costs by 70%.
What didn't
Wet roads, strong shadows and road edges without markings were the hard cases. Those are exactly the scenes a driver-assistance system cares about most, so they went to people, not to the model.
Keep reading
All posts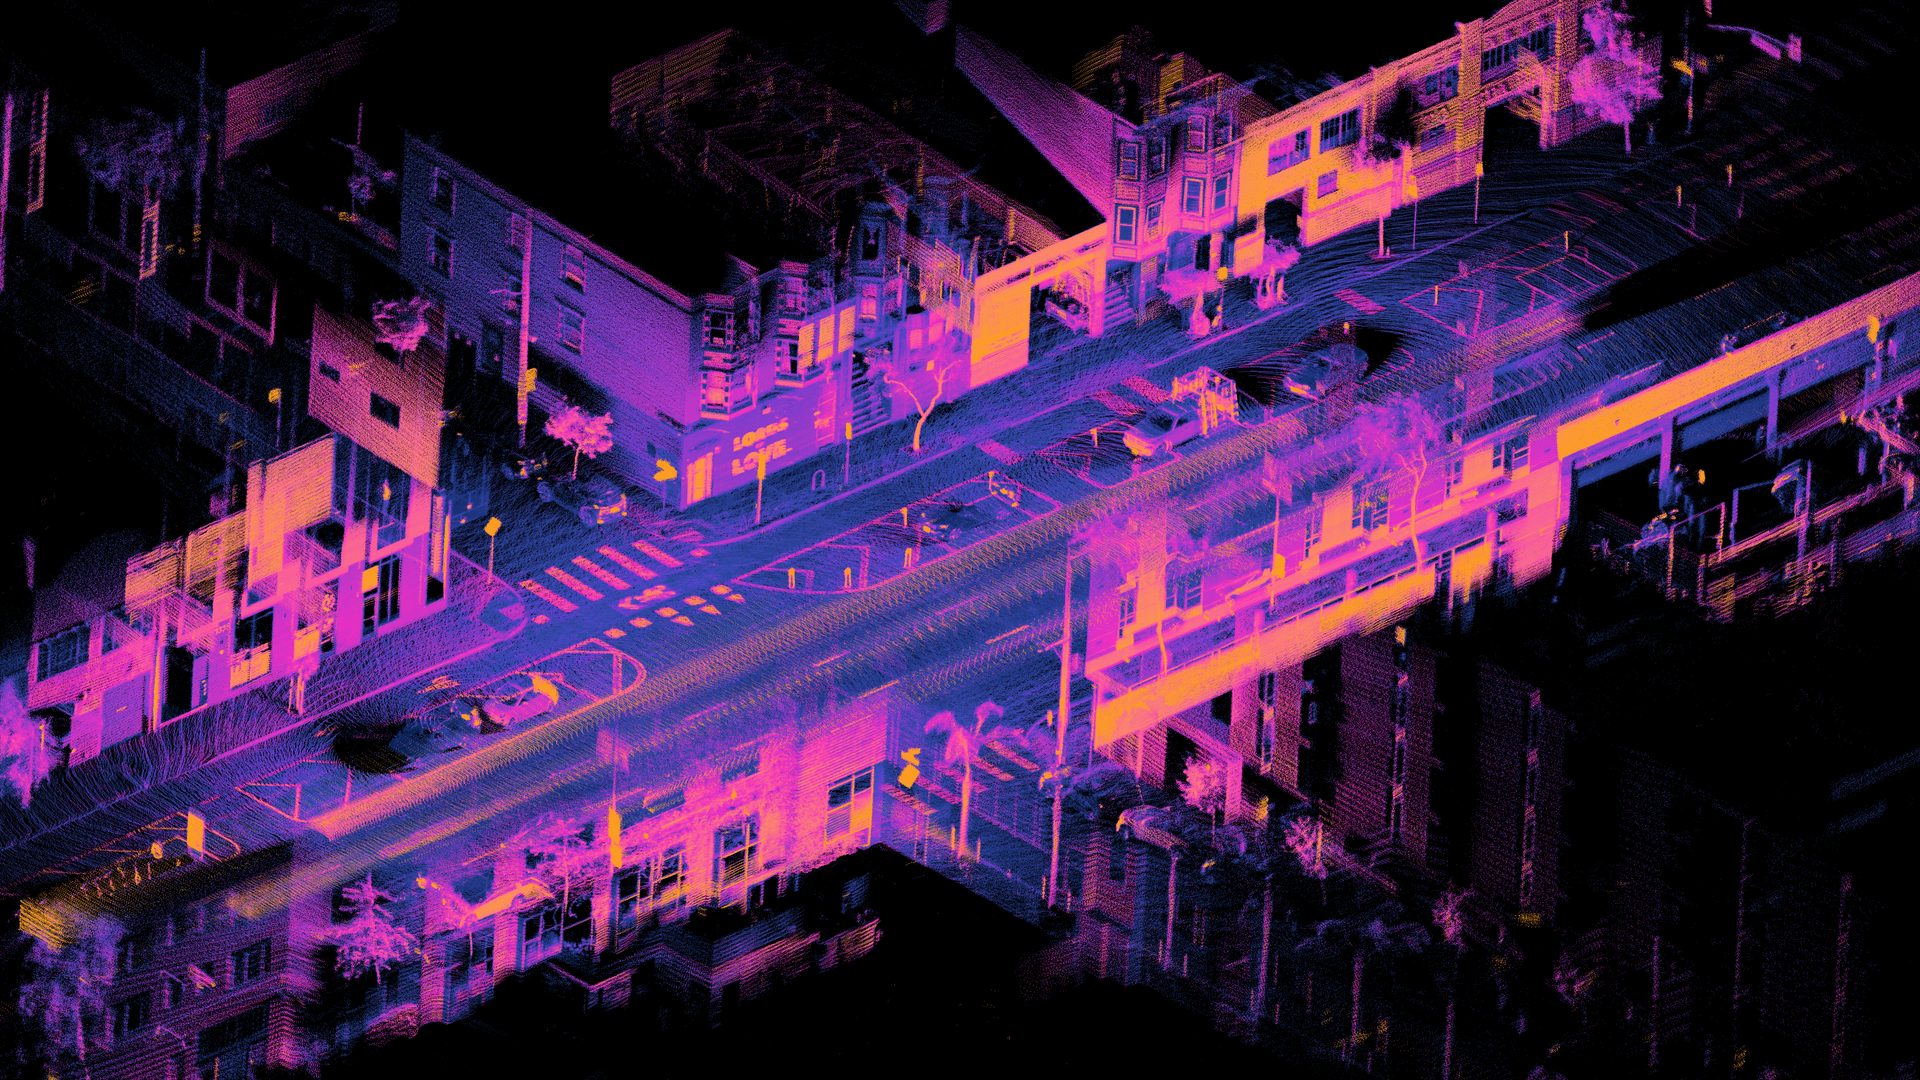
Auto-annotating camera and LiDAR data with foundation models
Labelling camera and LiDAR data is slow and expensive. How foundation-model pre-labels and camera-LiDAR fusion speed it up without lowering quality.
How to evaluate a RAG system without fooling yourself
A high retrieval score can still hide wrong answers. The reference sets, metrics and release gate I use to know whether a RAG change made answers better.
Running open-weight LLMs on your own GPUs
When health data cannot leave the building, the model has to come to the data. What self-hosting open-weight LLMs costs, and what it buys you.