Running open-weight LLMs on your own GPUs
When health data cannot leave the building, the model has to come to the data. What self-hosting open-weight LLMs costs, and what it buys you.
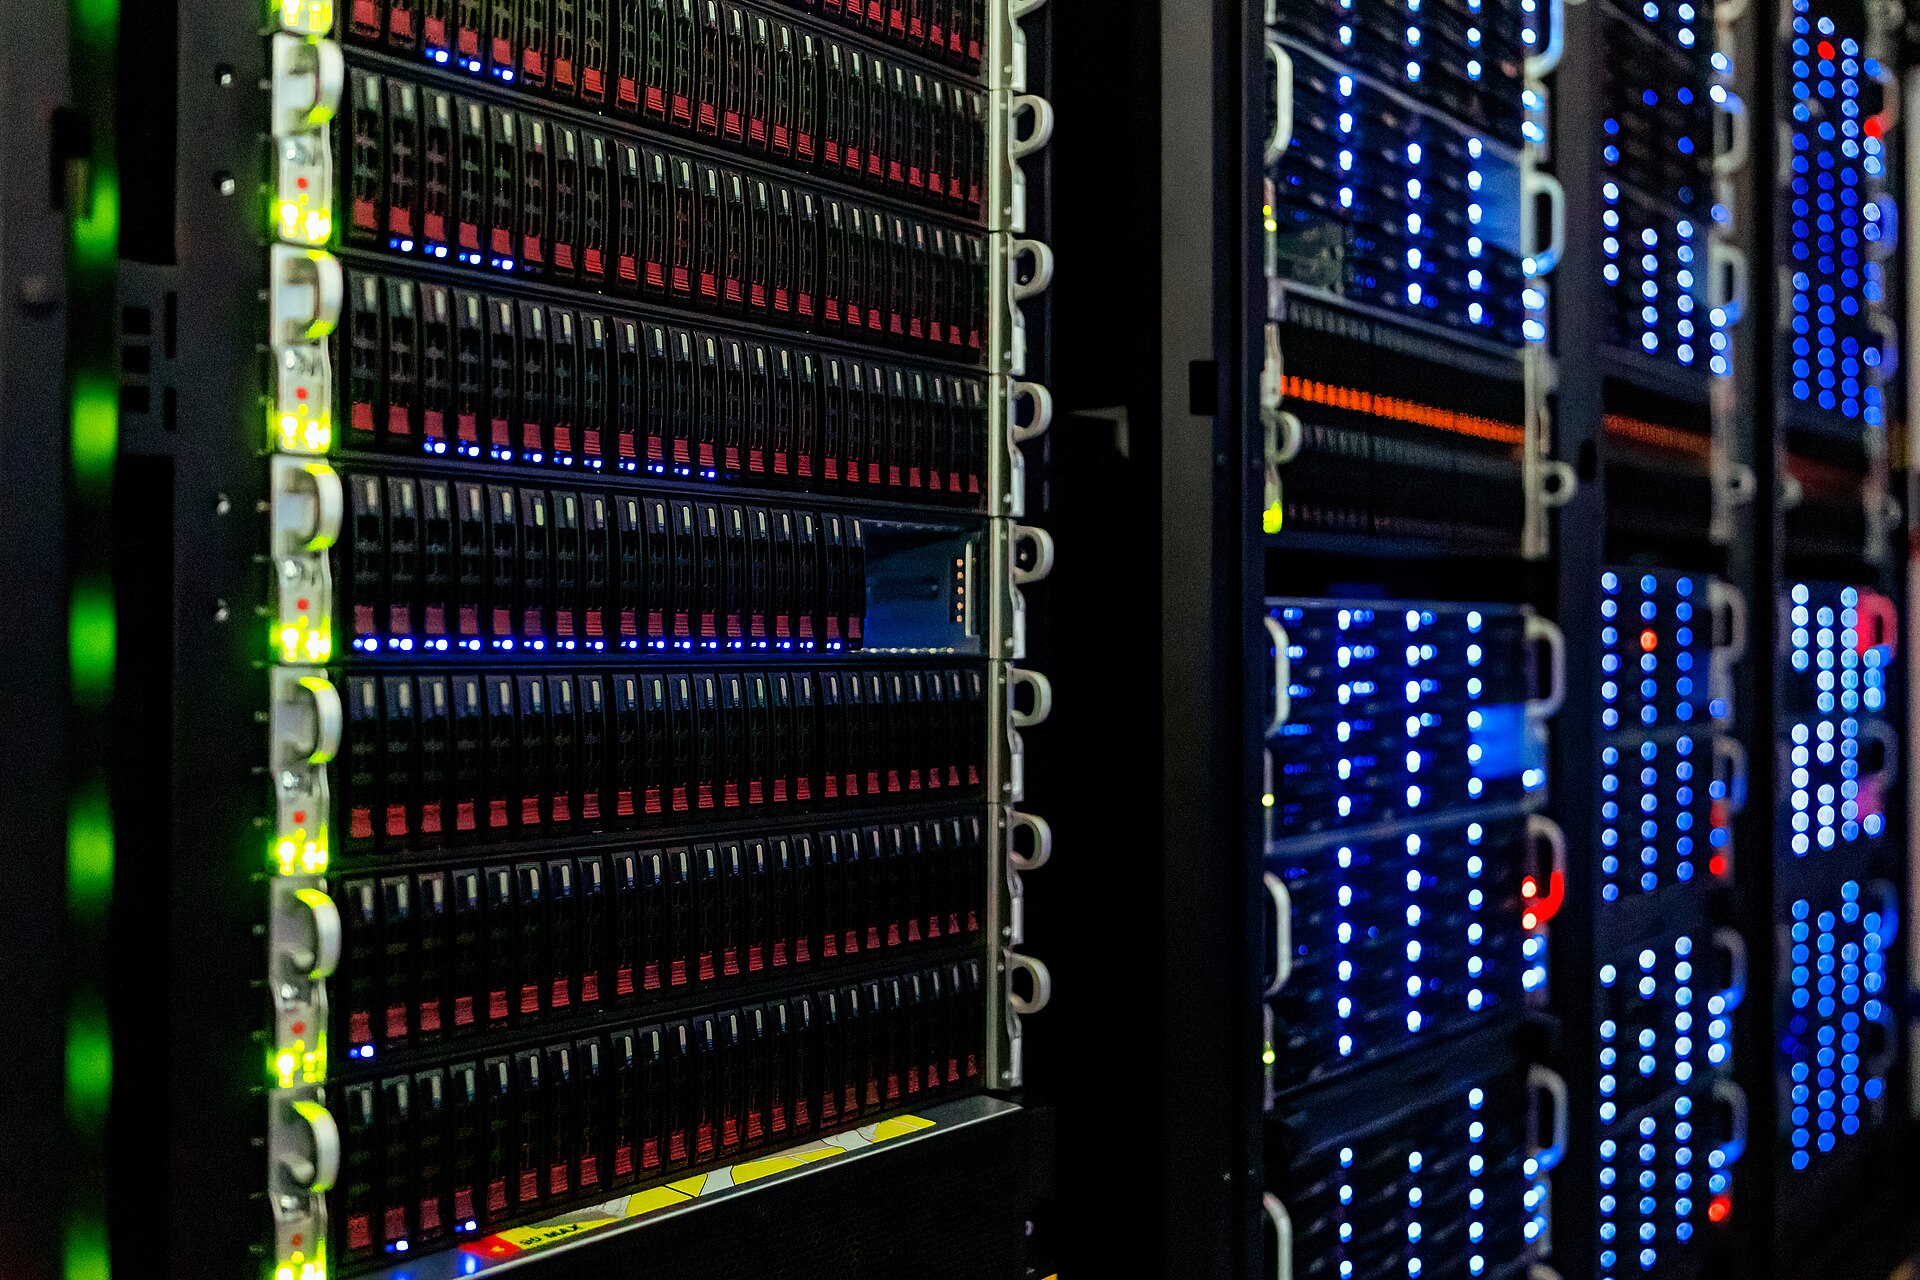
For most teams the first LLM in production is an API call. In health, that is often not allowed: patient records and internal procedures cannot be sent to a third party. The alternative is to run open-weight models on your own hardware.
What you take on
Self-hosting moves work onto your team that a provider used to do:
- Capacity planning. GPU memory decides which models fit, and how many requests run at once.
- Serving. An inference server with batching and streaming, monitored like any other service.
- Upgrades. A new model version is a deployment, with its own evaluation run before it ships.
What you get back
- Data that never leaves the building, which is often the only way the project gets approved.
- Predictable cost: the GPUs cost the same whether usage doubles or not.
- Control over latency. On the on-prem system I work on, answers got 40% faster over the project.
Choosing the model
Bigger is not automatically better on your own GPUs. I compare candidate models on the same reference set used for every release (see how I evaluate RAG), and pick the smallest one that passes the release gate.
Keep reading
All posts
How to evaluate a RAG system without fooling yourself
A high retrieval score can still hide wrong answers. The reference sets, metrics and release gate I use to know whether a RAG change made answers better.
Hybrid search: when BM25 beats embeddings
Embeddings miss exact codes, product names and section numbers that keyword search finds at once. Why my RAG systems combine BM25 and vector search.
Human approval steps for LangGraph agents
An agent that sends reports or changes records should stop and ask first. How I build approval steps, retries and tracing into LangGraph workflows.